Part 4 · Advanced Play: A/B Testing and Beyond · Chapter 13
Running an A/B Test
"Never guess what people will choose when you can measure what they actually do. Settle arguments not with volume, but with randomized data."
The mystery
The Great Button War of the Lab
The shouting match in the laboratory had reached seventy-eight decibels.
You were standing on the left side of the workbench, holding a sheet of graph paper. Your friend Leo was standing on the right side, waving a red marker in the air like a battle flag.
"It has to be blue!" you insisted, pointing at the laptop screen. "Look at it! A clean, crisp, royal-blue button with tidy white lettering that says [ Play Game ]. It looks professional. It looks trustworthy! Every serious player will click it!"
"Trustworthy?!" Leo sputtered, his eyes wide with disbelief. "Nobody wants trustworthy when they’re sitting down to battle pixel dragons! Trustworthy is what you want on an electric bill! We need excitement! We need adrenaline! We need a pulsing, neon-gold starburst button with lightning bolts that says: [ ⚡ Play Epic Quest! ]"
        THE GREAT BUTTON DISPUTE: TWO VISIONS COLLIDE

          Your Design (The Clean Control):
          ┌────────────────────────────────────────┐
          │             [ Play Game ]              │
          └────────────────────────────────────────┘
          "Professional! Minimalist! Tidy!"

          Leo's Design (The Epic Treatment):
          ┌────────────────────────────────────────┐
          │         [ ⚡ Play Epic Quest! ]         │
          └────────────────────────────────────────┘
          "Thrilling! Action-packed! Glitzy!"
"A gold starburst looks like spam from 2004!" you retorted.
"A blue rectangle looks like an insurance application from 1991!" Leo fired back.
"Blue!"
"Gold!"
"BLUE!"
"GOLD!"
Suddenly, a high-pitched siren chirped from the center of the desk. Agent Spark shot straight up toward the ceiling, his aluminum sphere spinning so fast that his cooling vents whistled. His dual LED eyes flashed an alarming shade of amber.
"Alert! Acoustic sensor warning!" Spark announced, his robotic voice clipping through the speakers. "Decibel levels indicate imminent human friendship degradation! My logic processors have detected a catastrophic biological loop: two intelligent primates arguing about human preferences using zero empirical observations!"
Leo crossed his arms. "Spark, tell them. Kids love gold buttons."
"Counter-query!" Spark whirred, hovering down to eye level. "How do you know kids love gold buttons? Have you interrogated all four hundred million video-game-playing children on planet Earth?"
"Well... no," Leo muttered. "I asked my cousin Kevin yesterday. Kevin said gold is awesome."
"Sample size: one cousin!" Spark beeped, throwing his tiny mechanical hands in the air. "Kevin's preference represents zero point zero zero zero zero zero two percent of the gaming population! Chief Scientist, Leo: in our laboratory, we do not shout. We do not make wild guesses based on cousins named Kevin. When two hypotheses clash, there is only one scientific path forward."
Spark's LED eyes flared into a radiant green.
"WE RUN AN A/B TEST!"
Figure 13.1: An arcade entrance split into two test corridors: 50% of incoming player avatars see Variant A (Blue) and 50% see Variant B (Gold), feeding live conversion meters.
In this chapter, you and Agent Spark will learn the most powerful experimental method in modern software engineering, web design, medicine, and behavioral science: the A/B test. By the end of this chapter, you will never argue about opinions again—because you will know how to let empirical reality decide the winner.
Unplugged lab
The Living-Room Snack Wording Experiment
Before we write code to simulate thousands of players online, let's run an unplugged, physical A/B test in your living room or kitchen.
We will test a profound psychological question: Does changing the words you use alter human decision-making, even when the underlying reward is identical?
       ================ THE UNPLUGGED SNACK A/B TEST ================

                           Incoming Test Subject
                                    │
                                    ▼
                         [RANDOM COIN FLIP]
                           /           \
                 HEADS    /             \    TAILS
                         ▼               ▼
                 [ VARIANT A ]     [ VARIANT B ]
                 "Would you like   "Would you like an
                  a snack?"         Adventure Power Crunch?"
                         │               │
                         ▼               ▼
                  [ TALLY LOG ]     [ TALLY LOG ]
                  Accepted: [ ]     Accepted: [ ]
                  Declined: [ ]     Declined: [ ]
Materials Needed:
1 Coin (A quarter or penny) for true randomization.
Identical Snacks on a clean plate (e.g., sliced apples, pretzel sticks, or baby carrots).
1 Index Card / Script Card with the two experimental prompts written down.
1 Tally Sheet / Clipboard (or your lab notebook).
Test Subjects (Family members, friends, neighbors, or classmates—at least 10 to 20 trials).
Great minds of the lab
Florence Nightingale and the Power of Comparative Data
When most history textbooks mention Florence Nightingale (1820–1910), they describe "The Lady with the Lamp"—a gentle, compassionate nurse walking quietly through dark hospital wards at night, soothing wounded soldiers during the Crimean War.
That story is true, but it leaves out Nightingale's true superpower.
Florence Nightingale was a fierce, brilliant, pioneering applied statistician and data scientist. She was the first woman elected to the Royal Statistical Society, and she transformed human medicine not with gentle whispers, but with comparative empirical telemetry.
                FLORENCE NIGHTINGALE'S POLAR AREA "ROSE" DIAGRAM
                             (Crimean War Telemetry)

                                   [ MARCH 1855 ]
                                   Reforms Begin!
                                        ▲
                                      /   \
              [ BEFORE: Variant A ]  /     \  [ AFTER: Variant B ]
              Preventable Disease   /       \ Sanitary Treatment
              Kills 42% of Soldiers!|       | Mortality Drops to 2%!
                                    \       /
                                     \     /
                                      \   /
                                        ▼
             "Ten times more soldiers died from dirty hospital air,
              bad food, and foul sewers than from Russian cannonballs!"
The Horror at Scutari
In November 1854, Nightingale arrived at the British Army Barrack Hospital in Scutari (modern-day Istanbul). What she found was a nightmare:
Digital sandbox
The Button Lab Simulator
Now let us return to the Great Button War between you and Leo.
Below is the complete, production-grade statistical engine:
Chapter 13 Notebook Summary
An A/B test compares a control against a single-variable treatment using randomized 50/50 allocation.
Never settle design arguments by shouting; settle them with randomized empirical data!
Small sample sizes (N<30) are dominated by random coin-flip noise and false positives.
Large sample sizes (N≥1,000) provide statistical significance (p, confidence).
Like what you see?
Register for free to run the experiments, make predictions and solve the bug-detective cases. Your work is saved on your device and syncs to your account.
Variant A (The Control): The plain, baseline wording.
Script: "Hello! Would you like a snack?"
Variant B (The Treatment): The adventurous, evocative wording.
Script: "Hello! Would you like an Adventure Power Crunch?"
[!IMPORTANT]
The snack on the plate MUST be 100% identical for both variants! If you offer apples for Variant A and chocolate cookies for Variant B, you have committed the cardinal sin of introducing a confounding variable. You won't know if they chose Variant B because of the words or because of the chocolate!
Step 2: The Randomized Coin Flip (The Traffic Router)
Whenever a person enters the room (or when you approach a participant), step aside where they cannot see you and flip the coin:
HEADS: You must deliver Variant A.
TAILS: You must deliver Variant B.
Why flip a coin? Because human experimenters have subconscious bias! If you secretly want Variant B to win, you might unconsciously choose hungry-looking people for Variant B and full people for Variant A. The coin eliminates your bias!
Step 3: Standardize the Delivery
Deliver your assigned line using the exact same tone of voice, neutral facial expression, and posture. Hold out the plate.
If they take a snack, record a YES (Conversion).
If they say "No thanks," record a NO (Bounce).
Tally Worksheet:
Participant #
Coin Flip (H/T)
Assigned Variant
Accepted Snack? (YES / NO)
Notes / Observations
1
H
Variant A
[ ] YES [ ] NO
Looked confused
2
T
Variant B
[ ] YES [ ] NO
Smiled and took two
3
T
Variant B
[ ] YES [ ] NO
Said "What kind of power?"
4
H
Variant A
[ ] YES [ ] NO
Said "Not right now"
5
T
Variant B
[ ] YES [ ] NO
Took a pretzel stick
6
H
Variant A
[ ] YES [ ] NO
Took a pretzel stick
Calculating Your Empirical Conversion Rates:
Once you have run at least 10 to 20 trials, calculate the conversion rates:
Conversion RateA=Total Visitors Assigned to ATotal YES for A×100
Conversion RateB=Total Visitors Assigned to BTotal YES for B×100
Troubleshooting & Observation Guide:
Contamination Confounder: If Participant 2 overhears you say "Adventure Power Crunch" to Participant 1, their response is no longer independent. Always test participants individually in separate rooms!
Satiety Confounder: If you run Variant A before dinner and Variant B after dinner, hunger levels will corrupt your data. The coin flip ensures that both variants are tested at identical times!
Wounded soldiers lay on unwashed wooden floors soaked in filth.
Open cesspools and broken sewer pipes leaked beneath the building.
Fleas, lice, and rats swarmed the wards.
Gangrene, cholera, and typhus spread like wildfire.
Army generals and government officials back in London assumed that young soldiers were dying because battle was brutal. They believed cannonballs, rifle shots, and saber cuts were responsible.
Nightingale refused to accept their assumptions. She pulled out a clipboard and began collecting empirical telemetry.
The Comparative Telemetry Breakdown
Nightingale categorized every single death into three clear buckets:
Blue/Gray Wedge: Deaths from preventable zymotic diseases (infections caused by filthy water, foul air, and unwashed hands).
Red Wedge: Deaths from direct battle wounds.
Black Wedge: Deaths from all other causes.
When she tallied the numbers, the data revealed an astonishing truth:
Out of thousands of deaths, less than 10% were caused by Russian bullets!
More than 85% of soldiers were dying from preventable infections caught inside the hospital itself!
        ┌────────────────────────────────────────────────────────┐
        │  NIGHTINGALE'S HISTORICAL A/B COMPARISON               │
        │                                                        │
        │  VARIANT A (Control: October 1854 – March 1855)        │
        │    Sanitation: Unwashed floors, toxic water, no drains │
        │    Mortality Rate: 42.7% (Catastrophic collapse)       │
        │                                                        │
        │  VARIANT B (Treatment: April 1855 – June 1856)         │
        │    Sanitation: Flushed sewers, boiled linens, fresh    │
        │                air ventilation, clean vegetables       │
        │    Mortality Rate: 2.2% (Historic triumph!)            │
        │                                                        │
        │  EMPIRICAL LIFT: Mortality dropped by over 40%!        │
        └────────────────────────────────────────────────────────┘
The Polar Area Diagram
The generals in the British War Department were stubborn, arrogant men who hated reading long tables of dry numbers. Nightingale knew that raw spreadsheets would be ignored.
So she invented a groundbreaking visual chart: the Polar Area Diagram (often called the Rose Diagram or Coxcomb).
In her diagram, each month was represented by a wedge radiating from the center like the petals of a flower. The size of each petal showed the number of deaths. The gigantic, sprawling blue petals from the early months showed massive deaths from filth (Variant A). Then, as her sanitation reforms took hold in spring 1855 (Variant B), the petals shrank dramatically to tiny slivers!
Queen Victoria and the British Parliament saw the diagram, understood the comparative data immediately, and ordered a total overhaul of military and civilian hospitals across the British Empire.
Florence Nightingale showed the world that when you measure Variant A against Variant B with clear, empirical telemetry, you don't just win an argument—you save millions of human lives.
The existing baseline system. It represents the "status quo." In our game, Variant A is your clean Blue Button: [ Play Game ].
2. The Treatment (Variant B)
The proposed modification. It has exactly ONE variable changed. In our game, Variant B is Leo's Gold Star Button: [ ⚡ Play Epic Quest! ].
3. The Randomized Traffic Allocator (The Digital Coin Flip)
Every time a new user visits the page, Agent Spark generates a pseudorandom floating-point number between 0.0 and 1.0:
if random.random() < 0.5:
    serve_variant("A")
else:
    serve_variant("B")
This guarantees an unbiased 50/50 split. Neither button gets an unfair advantage!
4. The Conversion Metric
The quantitative action we are measuring.
Did the user click the button?
A click is a Success (1).
Closing the tab without clicking is a Failure (0).
"""
Chapter 13: A/B Testing Statistical Simulator
Author: Dileep Pandey & Agent Spark
Demonstrates two-proportion hypothesis testing, z-scores, and p-values.
"""

import math
import random
from dataclasses import dataclass
from typing import Dict, Any


@dataclass
class Variant:
    """Represents an experimental branch in our A/B test."""
    name: str
    true_conversion_rate: float  # Ground-truth probability of a click (hidden from test)
    impressions: int = 0
    conversions: int = 0

    @property
    def observed_rate(self) -> float:
        """Calculates empirical conversion percentage."""
        if self.impressions == 0:
            return 0.0
        return (self.conversions / self.impressions) * 100.0


class ABTestSimulator:
    """
    Simulates incoming web traffic, performs randomized 50/50 routing,
    and computes two-proportion hypothesis test statistics.
    """
    def __init__(self, variant_a: Variant, variant_b: Variant):
        self.var_a = variant_a
        self.var_b = variant_b

    def simulate_visitors(self, total_visitors: int) -> None:
        """Routinely flips a coin for each incoming user."""
        for _ in range(total_visitors):
            # Randomized coin flip (50% traffic allocation)
            if random.random() < 0.5:
                # User routed to Variant A
                self.var_a.impressions += 1
                if random.random() < self.var_a.true_conversion_rate:
                    self.var_a.conversions += 1
            else:
                # User routed to Variant B
                self.var_b.impressions += 1
                if random.random() < self.var_b.true_conversion_rate:
                    self.var_b.conversions += 1

    def calculate_statistics(self) -> Dict[str, Any]:
        """
        Calculates the two-proportion z-score, p-value, and confidence interval.
        """
        n1 = self.var_a.impressions
        n2 = self.var_b.impressions
        k1 = self.var_a.conversions
        k2 = self.var_b.conversions

        if n1 == 0 or n2 == 0:
            raise ValueError("Cannot calculate statistics with zero impressions!")

        p1 = k1 / n1
        p2 = k2 / n2

        # 1. Pooled proportion under the null hypothesis (H0: p1 == p2)
        p_pool = (k1 + k2) / (n1 + n2)

        # 2. Standard error of the difference
        se_pool = math.sqrt(p_pool * (1.0 - p_pool) * ((1.0 / n1) + (1.0 / n2)))

        if se_pool == 0.0:
            z_score = 0.0
        else:
            # 3. Two-proportion Z-score
            z_score = (p2 - p1) / se_pool

        # 4. Standard normal cumulative distribution approximation (P-Value)
        # Using the Abramowitz and Stegun error function approximation
        p_value = 2.0 * (1.0 - 0.5 * (1.0 + math.erf(abs(z_score) / math.sqrt(2.0))))

        # 5. Statistical Confidence Percentage
        confidence_pct = max(0.0, (1.0 - p_value) * 100.0)

        # 6. Recommendation logic
        relative_lift = ((p2 - p1) / p1 * 100.0) if p1 > 0 else 0.0

        if confidence_pct >= 95.0:
            if p2 > p1:
                status = "STATISTICALLY SIGNIFICANT WINNER: Deploy Variant B!"
            else:
                status = "STATISTICALLY SIGNIFICANT WINNER: Retain Variant A!"
        elif confidence_pct >= 80.0:
            status = "TREND DETECTED: Insufficient sample size. Continue gathering data."
        else:
            status = "INCONCLUSIVE / HIGH NOISE: Random chance explains difference."

        return {
            "variant_a_impressions": n1,
            "variant_a_clicks": k1,
            "variant_a_rate": round(p1 * 100.0, 2),
            "variant_b_impressions": n2,
            "variant_b_clicks": k2,
            "variant_b_rate": round(p2 * 100.0, 2),
            "absolute_lift_pct": round((p2 - p1) * 100.0, 2),
            "relative_lift_pct": round(relative_lift, 2),
            "z_score": round(z_score, 3),
            "p_value": round(p_value, 5),
            "confidence_pct": round(confidence_pct, 2),
            "recommendation": status
        }


# =====================================================================
# LIVE EXPERIMENTAL VERIFICATION
# =====================================================================
if __name__ == "__main__":
    # Seed random for reproducible demonstration
    random.seed(42)

    print("=== LIVE CHAPTER 13 A/B TEST EXECUTION ===")
    blue_button = Variant("Control: Blue", true_conversion_rate=0.10)
    gold_button = Variant("Treatment: Gold", true_conversion_rate=0.15)

    experiment = ABTestSimulator(blue_button, gold_button)

    # Trial 1: Small Sample (N = 30)
    print("\n--- TRIAL 1: Small Sample (N = 30) ---")
    experiment.simulate_visitors(30)
    res_small = experiment.calculate_statistics()
    print(f"Rates: A={res_small['variant_a_rate']}% vs B={res_small['variant_b_rate']}%")
    print(f"Confidence: {res_small['confidence_pct']}% | Status: {res_small['recommendation']}")

    # Trial 2: High Sample (Add 1,200 more visitors)
    print("\n--- TRIAL 2: Large Sample (N = 1,230) ---")
    experiment.simulate_visitors(1200)
    res_large = experiment.calculate_statistics()
    print(f"Rates: A={res_large['variant_a_rate']}% vs B={res_large['variant_b_rate']}%")
    print(f"Confidence: {res_large['confidence_pct']}% | Status: {res_large['recommendation']}")
Statistical Walkthrough for Young Researchers:
The Z-Score (Line 67): The z-score measures how many standard deviations the observed difference sits away from zero.
If z<1.0: The difference is tiny and easily explained by random coin flips.
If z≥1.96: The difference corresponds to the magical 95% confidence threshold!
The P-Value (Line 71): The p-value represents the probability that random chance alone could have created this difference. When p<0.05 (less than 5% chance of random luck), scientists reject the "Null Hypothesis" and declare a true discovery!
The Error Function (math.erf on Line 71): This standard mathematical function calculates the area under the bell curve (the Gaussian normal distribution).
<
0.05
95%+
In Chapter 14, we dive deeper into telemetry to measure what players actually experience: Metrics for Fun!
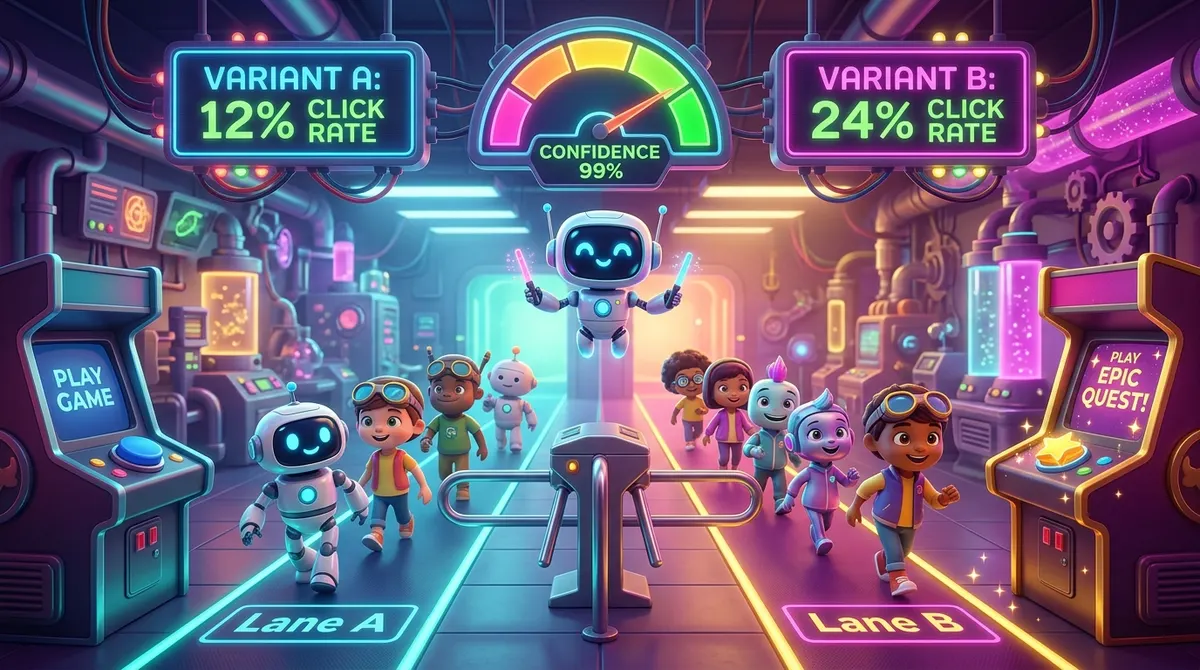 Figure 13.1: An arcade entrance split into two test corridors: 50% of incoming player avatars see Variant A (Blue) and 50% see Variant B (Gold), feeding live conversion meters.